
Claude Fable 5.1 is Anthropic's newest model, released the first week of September 2026 as an update to Fable 5, the top tier of Anthropic's model lineup, built for coding and complex knowledge work. Fable 5.1 and its more permissive sibling, Mythos 5.1, are the same underlying model running behind different safeguard layers. Fable 5.1 is generally available to anyone on a paid Claude plan. Mythos 5.1 is restricted to vetted cybersecurity and life sciences professionals through Anthropic's verification programs.
The headline change is cost, not just capability. Cached input tokens (repeated context Claude doesn't have to reprocess from scratch each time) now cost 75% less, and Anthropic says a typical workload runs about 25% cheaper overall, up to 45% cheaper for heavily agentic tasks (work where the model plans, acts, checks its own output, and keeps going without a person steering every step) that lean hard on that cache. Underneath the price cut, Fable 5.1 posts real gains on the benchmarks that measure exactly that kind of extended, self-directed work.
The quick answer
- Claude Fable 5.1 launched September 2026, priced at $10 per million input tokens and $50 per million output tokens, unchanged from Fable 5, with cached reads dropping from $1.00 to $0.25 per million tokens.
- It's built for agentic coding and scientific research: extended unattended runs, debugging real production issues, and lab-style work like protein design and planetary mapping.
- Mythos 5.1 is the same model with fewer restrictions, for vetted cybersecurity and life sciences use. Everyone else gets Fable 5.1.
What's new in Claude Fable 5.1
Compared with Fable 5, the gains show up most in benchmarks built to measure agentic work rather than single-turn answers:
- Agentic scientific research (Terminal-Bench-Science): 52.6% versus 24.7% for Fable 5, more than double.
- Agentic coding (Terminal-Bench 4.0): 55.8% versus 42.0%.
- Automated workflows (AutomationBench): 31.4% versus 17.1%.
- Multidisciplinary reasoning (Humanity's Last Exam, with tools): 65.0%, ahead of GPT-6 Astra's 57.2% on the same test.
Both models share a 1 million token context window (the amount of text Claude can hold in mind at once during a conversation or task) with up to 128,000 tokens of output, and "adaptive thinking" that stays on by default rather than something you switch on for harder problems.
Claude Fable 5.1 vs Claude Mythos 5.1: what's different
Fable 5.1 and Mythos 5.1 run on the identical model. The difference sits entirely in the safeguard layer on top of it. Mythos 5.1's cybersecurity safeguards trigger around 60% fewer interventions per session, and its biology safeguards trigger 85% less often on requests that turn out to be benign, which matters if you're a legitimate security researcher or life sciences team getting blocked by false positives under the standard model. Anthropic keeps Mythos 5.1 restricted to vetted U.S. organizations through its Cyber Verification Program and Life Sciences Verification Program specifically because those loosened safeguards are also what would make it more useful to someone trying to cause harm. If you don't already qualify for one of those programs, Fable 5.1 is the version you'll use, and for nearly everything outside specialized security or biology research, it's the right one anyway.
What it's being used for
Debugging a years-old production crash
Millennium, an early access partner, used Fable 5.1 to resolve a rare software crash in external vendor code that had resisted explanation for years. That's the kind of problem where the code isn't yours, the vendor can't reproduce it, and a human engineer would normally need days of isolated testing to even locate the cause.
Working unattended for a day and a half
Ramp, another early access partner, documented a 38-hour unattended run where Fable 5.1 conducted experiments and proposed next steps on its own, without a person checking in between. That's the practical shape of an agentic session: hours of steps toward one goal, largely unsupervised.
Scientific research
Anthropic's own testing, run through Mythos 5.1, the less-restricted version, produced results in three areas. It designed protein binders (molecules engineered to attach to a specific target protein) with binding affinities 10 times higher than the best entries in outside competitions, close to a 50% hit rate against the 10% to 15% that's typical. It built a high-resolution elevation map covering a third of the surface of Venus, accurate down to 2 to 3 kilometers, a 25% improvement over prior maps. And it made seven deep learning models used in computational biology run up to 2.5 times faster, cutting the GPU costs of genome-wide analysis by 30% to 60%.
Everyday knowledge work
Outside the lab, early access reports point to contract redlining and financial analysis, investigating production incidents as they happen, and developing research hypotheses before a person decides which ones are worth pursuing.
Does Claude Fable 5.1 watermark what it writes?
Yes. Anthropic builds invisible watermarking into everything Claude generates, plus a detection API currently in private preview, largely to meet EU transparency requirements around AI-generated content. If you use Claude for writing and want the full picture of how that watermarking works and what it means for your own writing, we covered it in a separate post.
What Claude Fable 5.1 costs, and is it free
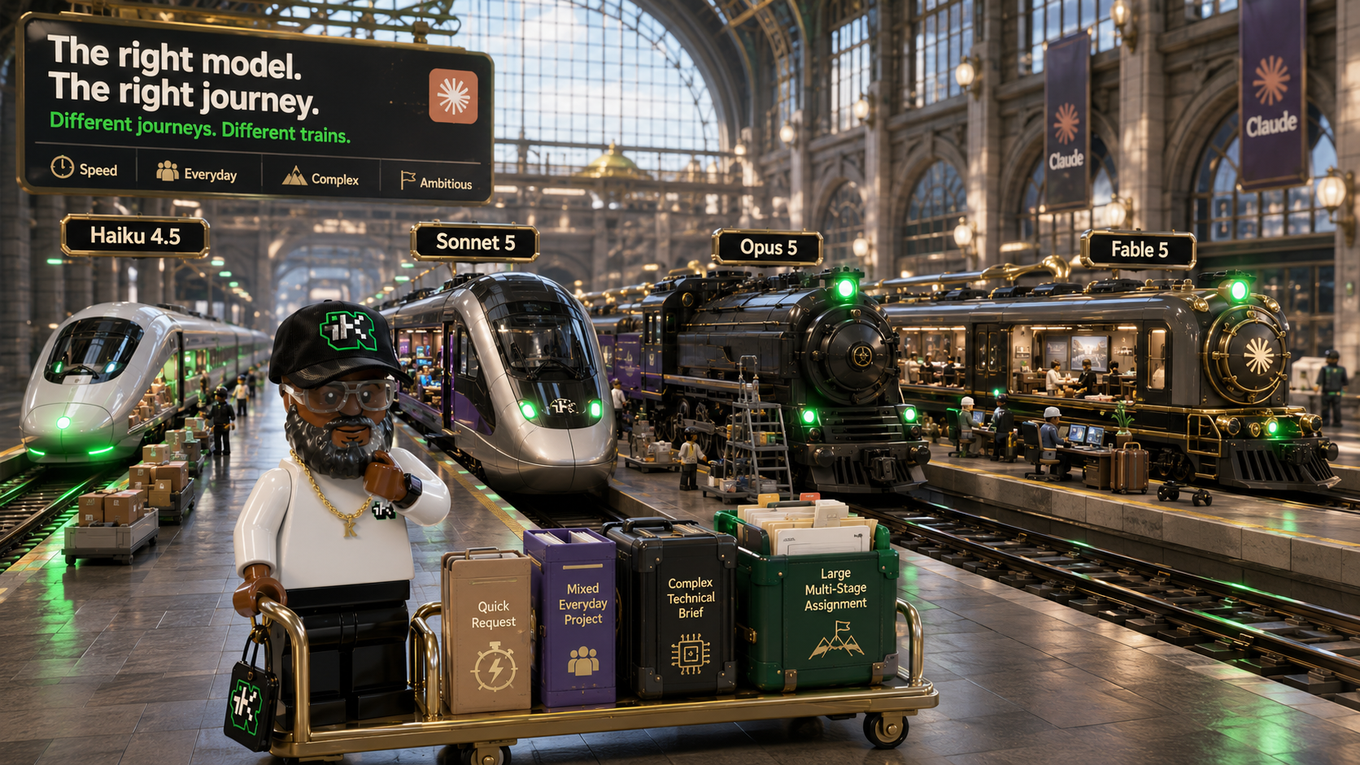
There's no free tier. Fable 5.1 runs on Claude's paid plans, at the same $10 per million input tokens and $50 per million output tokens as Fable 5. The change is in caching: reading from cache now costs $0.25 per million tokens instead of $1.00, a 75% cut, and Anthropic says that drops the cost of a typical workload by about 25%, more for tasks that repeat a lot of context. For scale, that's more expensive per uncached token than Claude Sonnet 5 ($2 in, $10 out per million) or Claude Opus 5 ($5 in, $25 out), which tracks with Fable's position at the top of Anthropic's lineup, but its cached reads cost half what Opus 5 charges.
Where to get it
Fable 5.1 is live now on Claude.ai, the Claude API, and through Amazon Web Services, Google Cloud, and Microsoft Azure. Mythos 5.1 is only available through the Cyber Verification Program and Life Sciences Verification Program, currently limited to select U.S. organizations. Zero data retention stays available for eligible customers until Anthropic's Enterprise Frontier Safeguards, a feature letting enterprise customers keep monitoring data on their own cloud infrastructure with their own encryption keys, rolls out this fall.
Should you use Claude Fable 5.1
If you're already paying for Claude and doing agentic work, coding tasks that run for a while unattended, research that leans on tool use, or anything caching-heavy, the price drop alone makes switching worth testing (see our breakdown of Claude's other models if you're new to how Anthropic names things). If your work is lighter, quick questions, everyday writing, simple summaries, Claude Sonnet 5 costs less and won't leave much on the table. And if you're weighing it against what OpenAI just shipped, GPT-6 Astra came out the same week with its own tradeoffs, including a stronger showing on computer-use tasks and a rougher one on the science-heavy version of Humanity's Last Exam.
Sources:
anthropic.com/claude-fable-and-mythos-5-1 ·
venturebeat.com/anthropics-claude-fable-5-1-and-mythos-5-1 ·
marktechpost.com/anthropic-releases-claude-fable-5-1-and-claude-mythos-5-1 ·
macrumors.com/2026/09/01/anthropic-claude-fable-5-1